Classification
Label leads, tickets, risk, or quality outcomes with models tuned to your classes and costs.
echoBitz designs and trains custom AI Agent and machine learning models around your business problem. Feature engineering, validation, and monitoring turn predictions into outcomes you can measure.
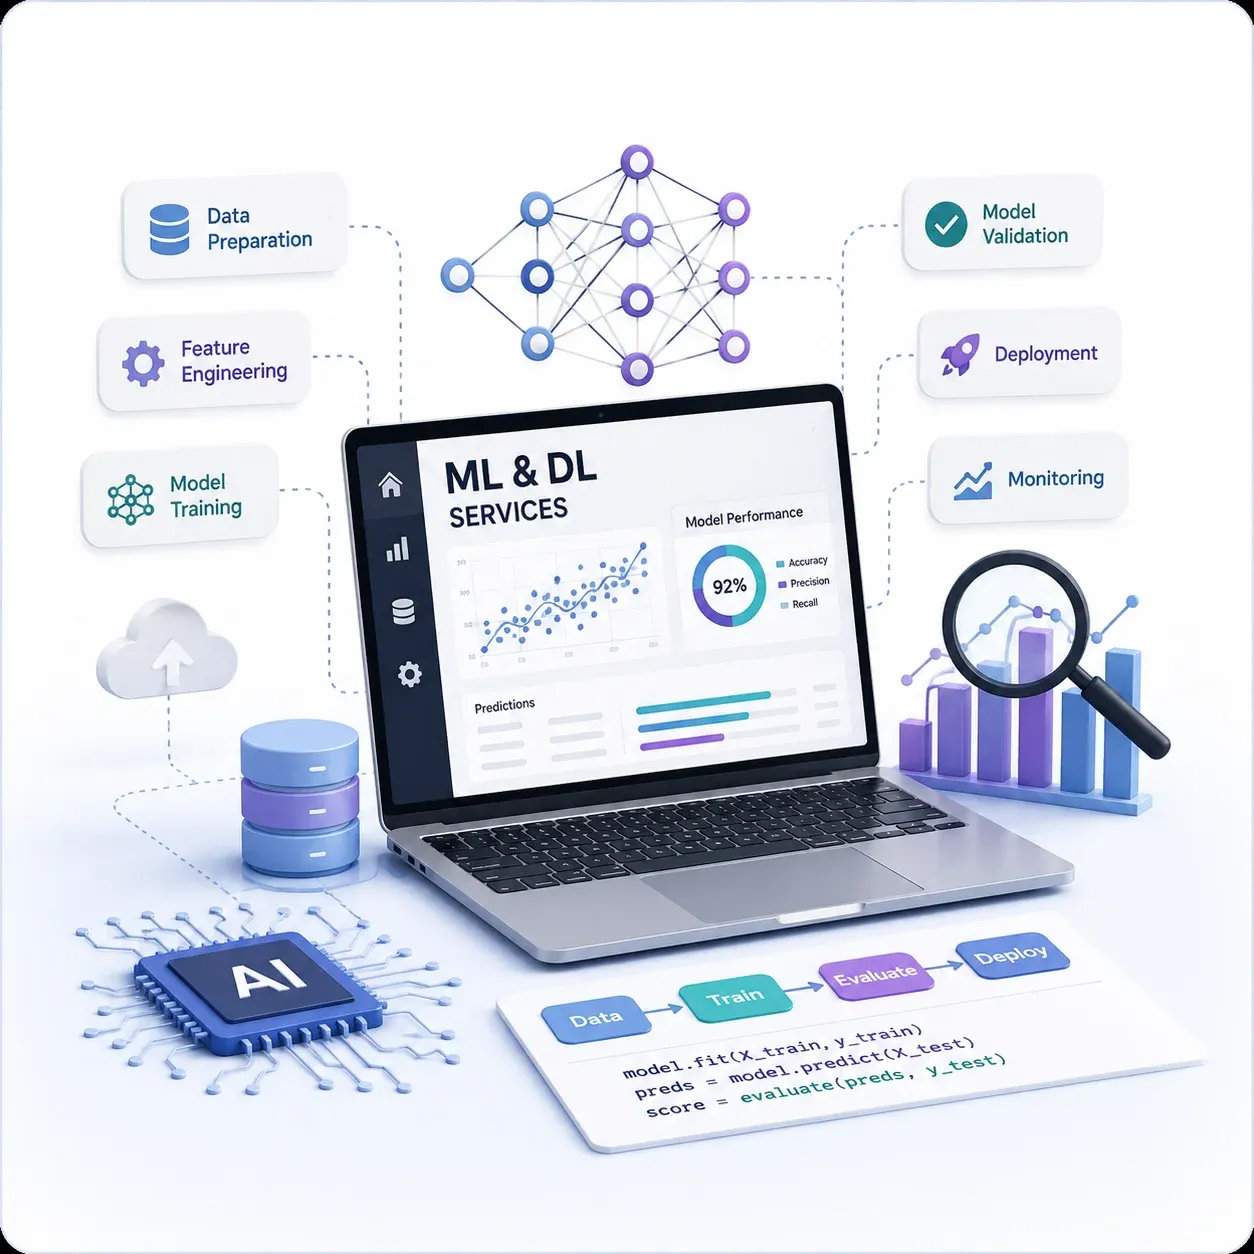
From classification to anomaly detection scoped to your data and KPIs.
Label leads, tickets, risk, or quality outcomes with models tuned to your classes and costs.
Predict continuous values demand, price, duration, or spend with clear error bounds.
Time-series models for inventory, capacity, and revenue planning horizons.
Segment customers, products, or behaviors when labels are incomplete or evolving.
Prioritize opportunities, recommendations, or work queues by learned relevance.
Surface unusual transactions, sensor readings, or process deviations early.
A disciplined path so models ship with metrics not just notebooks.
Define the decision, success metric, and data reality with stakeholders.
Clean, join, and engineer features; set train / validation / test splits.
Select algorithms, tune hyperparameters, and track experiment runs.
Holdout evaluation, error analysis, and business-rule checks before release.
Serve predictions via API or batch jobs with monitoring and retraining plans.
Pragmatic stack choices matched to your latency, data shape, and team skills.
We do not optimize a vanity score in isolation. Precision, recall, F1, MAE, or AUC are chosen against how false positives and false negatives hit your process.
How often positive predictions are correct critical when false alarms are expensive.
How many true cases you catch critical when misses are costly.
Balanced view when both precision and recall matter to the workflow.
Ranking quality or regression error picked to fit the model type.
Artifacts you can operate not a one-off demo notebook.
Decision definition, success metrics, and data assumptions documented.
Reproducible transforms from raw sources to model-ready inputs.
Versioned model artifacts with training configuration recorded.
Holdout metrics, error analysis, and known limitations.
API or batch scoring wired into your application or data stack.
Drift signals, retraining triggers, and ownership after go-live.
We build custom models with the same delivery discipline as our ERP and automation work. Clear metrics and integration paths give your team a handover it can own.
We start with the operational outcome and establish an honest baseline. Then we engineer the data, model, deployment, and ownership path as one production-ready system.
Straight answers on custom ML scope, data needs, timelines, and how echoBitz delivers models into production.
Start an ML ProjectProblem framing, data preparation, feature engineering, model training and validation, evaluation reporting, serving integration, and a monitoring / retraining plan scoped to your use case.
It depends on the problem and class balance. During discovery we assess volume, quality, and label availability, then recommend a realistic first model scope or a data-improvement path.
No. We choose classical ML or deep learning based on data shape, latency, and maintainability. Deep learning is used when it clearly earns its complexity.
Yes. We commonly expose scoring via APIs or batch jobs and wire results into Odoo, warehouses, or existing applications.
A focused pilot can land in a few weeks when data is accessible. Broader feature pipelines and production hardening typically span multiple sprints after discovery.
You do. We hand over artifacts, docs, and runbooks and can stay on for monitoring and retraining support if you want ongoing help.